GDPR Privacy Impact Assessment for API-Driven Products
API products face heightened GDPR scrutiny due to complex data flows.
GDPR fines have crossed €7.1 billion since 2018, and 2025 alone accounted for €1.2 billion of that total. More than 60% of every euro fined since January 2023 landed in roughly two years, which means regulators found their rhythm and are not slowing down. Breach notifications to European data protection authorities now arrive at 443 per day, up 22% year over year. Enforcement is no longer an occasional event.
Three cases from early 2026 illustrate the sector spread. A Dutch data protection authority fined the company behind Yango and Yandex €100 million on April 1, 2026, ruling that standard contractual clauses alone were insufficient cover for transfers into Russia. FC Barcelona received a €500,000 fine on March 4, 2026, over a biometric data DPIA that did not hold up under review, demonstrating that sports clubs face the same scrutiny as banks and telecoms. Yoti Ltd, an identity verification company, received a €950,000 fine on March 10, 2026, for processing biometric data without a valid legal basis, invalid consent, and retaining data beyond permissible periods. That case lands directly on age-verification and identity API vendors.
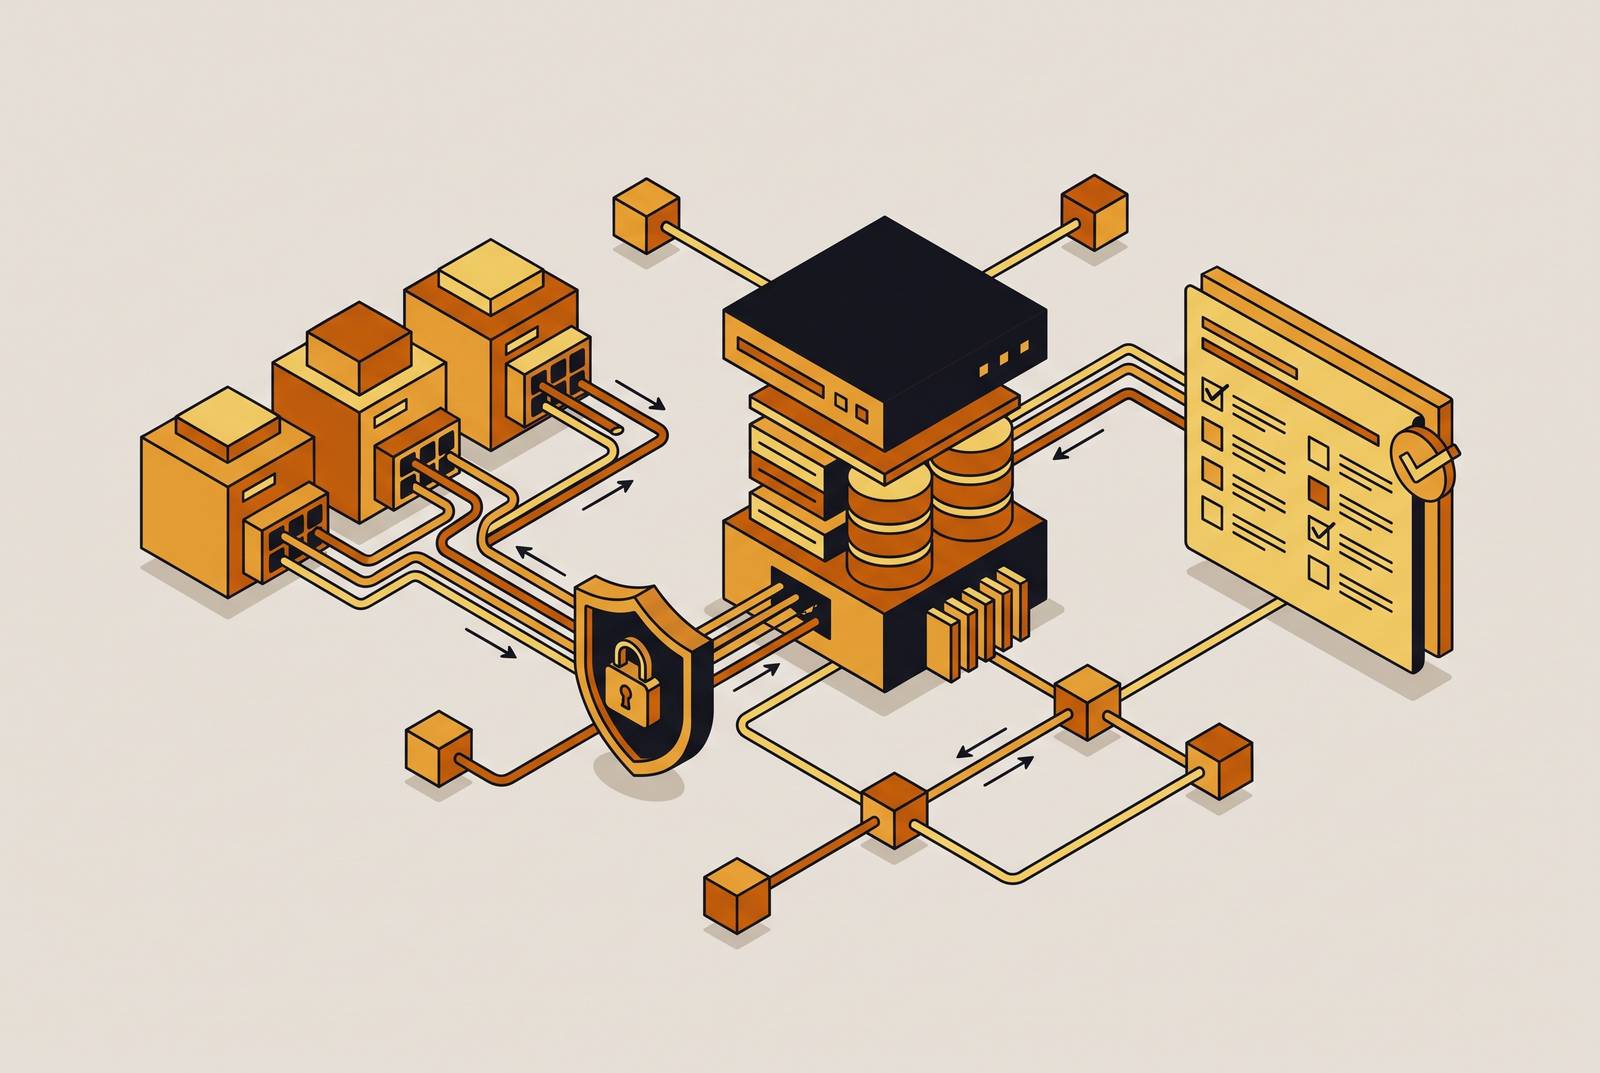
Compliance risk scales with how many hands touch data on the way through a system, not with how much data is collected. API products move personal data continuously, across processor chains stacked three or four vendors deep, often in real time, often crossing borders without anyone noticing. Layered chains, real-time transit, and cross-border hops are the specific factors regulators now cite as aggravating circumstances when calculating fines. A standard web app that stores a form submission in one database looks nothing like an API that distributes a user's request across six microservices, two of which operate in different countries. Regulators have begun treating that architecture as inherently riskier, and the enforcement record supports that position.
DPIA vs. General Privacy Impact Assessment
A DPIA is the specific legal instrument Article 35 of GDPR requires. A Privacy Impact Assessment predates GDPR, appears in non-EU privacy frameworks, and functions as a voluntary general checkup. A DPIA carries legal weight; a PIA carries good intentions. The regulation is explicit on timing: a DPIA must be completed before processing begins, not after.
One distinction specific to API products causes persistent confusion: only controllers are legally required to run a DPIA, not processors. An API company's role can shift feature by feature. A company might be the controller for its own user accounts and the processor for a customer's end-user data flowing through its API, sometimes simultaneously on the same platform depending on which endpoint was called. Determining which role applies to which feature is a prerequisite. Skipping it allows DPIA obligations to go unnoticed until an audit surfaces them.
When Your API Legally Triggers a DPIA
Article 35 sets the threshold at processing "likely to result in a high risk" to individuals. Scenarios that should trigger a DPIA immediately include: adding an AI or machine learning inference feature that scores, ranks, or flags users such as fraud signals, recommendation engines, or risk scores; building an analytics dashboard that aggregates behavior across a user base at scale; adding a biometric authentication endpoint; or expanding into health data, financial data, or any other Article 9 special category through a new integration.
Two scenarios get dismissed too often: logging a user ID for debugging, and storing a support ticket that contains a person's name. Developers tend to classify these as operational rather than processing activities. GDPR classifies both as processing.
Multi-tenant SaaS architecture introduces its own trigger that most generic DPIA checklists omit: a failure in cross-tenant data isolation, where a bug or misconfigured query exposes one customer's data to another. That is a structural risk inherent to the architecture, not a hypothetical edge case, and it warrants its own line item in any assessment.
Modification is a frequently overlooked trigger. Teams reliably identify the DPIA requirement at launch and reliably forget that changing an existing system, delegating high-risk processing to a new third party, or crossing a new volume threshold can all retrigger the obligation. A feature that shipped without issues can drift into DPIA territory without any corresponding update to the documentation.
Map Every Data Flow Before You Start
Only 33% of organizations know with real confidence where all their data lives. Regulators now treat full data visibility as a baseline requirement, not an optional improvement. Beginning a DPIA before completing this step undermines the entire assessment.
A proper data map for an API product must cover:
Every endpoint touching personal data, including internal service-to-service calls, not just public-facing ones
The exact categories of data moving through each endpoint, such as identifiers, behavioral signals, device fingerprints, and inferred attributes like risk scores
Retention at each hop, including data in transit, in logs, in caches, and in downstream third-party systems (many API providers default to retaining content for up to 30 days, a pattern that repeats across the industry)
Every third-party API, cloud processor, and analytics vendor with any access to the data
The exact points where data crosses out of the EU/EEA, which country it reaches, and which transfer mechanism governs that transfer
The most reliable method for building this map is to select one real user action and trace it from start to finish, following every service call it triggers, every log line it writes, and every message it places into an async queue. The output becomes a data flow diagram included as an exhibit in the DPIA. That diagram must remain a living document, because a static diagram becomes inaccurate as the system evolves.
Describe Processing Purposes with Article 35 Precision
Article 35 requires a systematic description of the processing operation covering its nature, scope, context, and purposes. For an API product, describing the nature of processing requires answering three concrete questions: Is any part of this automated versus human-reviewed? Does profiling or scoring occur anywhere in the pipeline, even as a secondary effect of something classified internally as analytics? If an AI inference layer is involved, is that model self-hosted or running on a third party's infrastructure?
Purpose limitation is a hard constraint. The DPIA must document that each API call processes data strictly for its stated purpose, and that a downstream third-party API cannot expand that purpose independently. Lawful basis also cannot be applied as a single label across an entire product. Most API products operate under several bases simultaneously: contract for the core feature a user enrolled in, legitimate interest for fraud detection running in the background, and legal obligation for audit logs retained until legally required. Applying one basis across the whole product will not survive a regulatory review.
Assess Necessity and Proportionality Across Processors
The necessity and proportionality test asks whether a processing activity achieves its stated purpose using the minimum data required. Data minimization is a design constraint that must shape architecture before implementation, not be added afterward.
A common issue in API products is that a single API call often carries more data than the feature requires, including headers, device fingerprints, session tokens, and log metadata with no functional purpose. Necessity must be assessed field by field, not endpoint by endpoint, because the necessity of an endpoint and the necessity of every field in its payload are two separate determinations.
For every processor in the chain, three questions require substantive answers. Does the vendor actually need raw personal data, or would pseudonymized or aggregated data produce the same result? Does the vendor's default retention period exceed what the feature requires? A vendor's default retention period may be far longer than a real-time inference call that only requires data for a brief moment. Does the vendor offer a data minimization configuration, and has it been enabled?
Data minimization should appear in the DPIA as a set of concrete engineering decisions: pseudonymizing data before it is sent to a third-party API, redacting specific fields at the point of collection, and using synthetic data in staging and test environments rather than real customer records.
Rate API-Specific Risks with a Structured Matrix
A risk matrix rates two dimensions for every identified risk: likelihood, ranging from improbable to very likely, and severity, ranging from minor to catastrophic. A sub-processor transferring EU health data to a jurisdiction with weak protections may be low-likelihood but catastrophic in impact. A debug log retaining a user ID slightly beyond policy may be high-likelihood but minor in impact. Those two risks require different mitigation approaches, and treating them identically reduces a risk register to a formality rather than a functional document.
API products carry a specific set of risks that belong on the register. Sub-processor chain opacity is typically the most significant: a controller often cannot observe what its processor's own sub-processor is doing with data several hops downstream. Processors are required to bind their sub-processors to protections equivalent to those in the original agreement, and if that chain breaks, the processor bears liability for the sub-processor's failures.
Real-time transit interception deserves its own entry. Data moving across API calls presents a different attack surface than data stored in a database and should not be treated as a footnote under general data-at-rest risks. Multi-tenancy isolation failure represents the structural risk noted earlier, where a query error allows one tenant's data to appear in another tenant's response. Purpose drift via third-party model updates is a risk that rarely appears on assessment schedules: a vendor pushes an update to its AI model, the inference behavior changes, and personal data is used differently than it was previously even though the controller made no change.
Cross-border transfer mechanism failure is not hypothetical. The EU-US Data Privacy Framework remains under active legal challenge before the CJEU, following a failed first challenge at the EU General Court in September 2025 and a subsequent appeal registered as Case C-703/25 P. If that adequacy decision is invalidated, a fallback transfer mechanism must already be in place before a ruling is issued.
Every entry on the register requires three data points: the risk rating before mitigation, the mitigation applied, and the residual rating after that mitigation is in effect. Regulators focus on the residual rating. The pre-mitigation rating describes what could go wrong; the residual rating shows what was actually done about it.
Govern Article 28 DPAs Across Every Processor
Article 28 specifies the required elements every Data Processing Agreement (DPA) must include. A missing element creates a legal vulnerability and a recurring objection in enterprise procurement reviews.
Those required elements must accurately describe the actual processing occurring in the actual product, as mapped in the preceding steps. A generic DPA that does not correspond to what the product does with data does not satisfy the Article 28 requirement regardless of its formatting or length.
Sub-processor management is where compliance frequently breaks down. Article 28(4) requires processors to bind their own sub-processors to protections equivalent to those in the original DPA, and controllers cannot assume that obligation was fulfilled somewhere upstream. Processors must also notify controllers when the sub-processor list changes. Anthropic's addition as a sub-processor to Microsoft 365 Copilot, effective January 7, 2026, is a direct example of that notification obligation in practice. Any organization that completed its Copilot DPIA before that date may be operating with an undocumented transfer path that its documentation does not reflect.