Breaking vs Non-Breaking API Contract Changes
Distinguish between breaking and non-breaking API changes before they damage consumer trust.
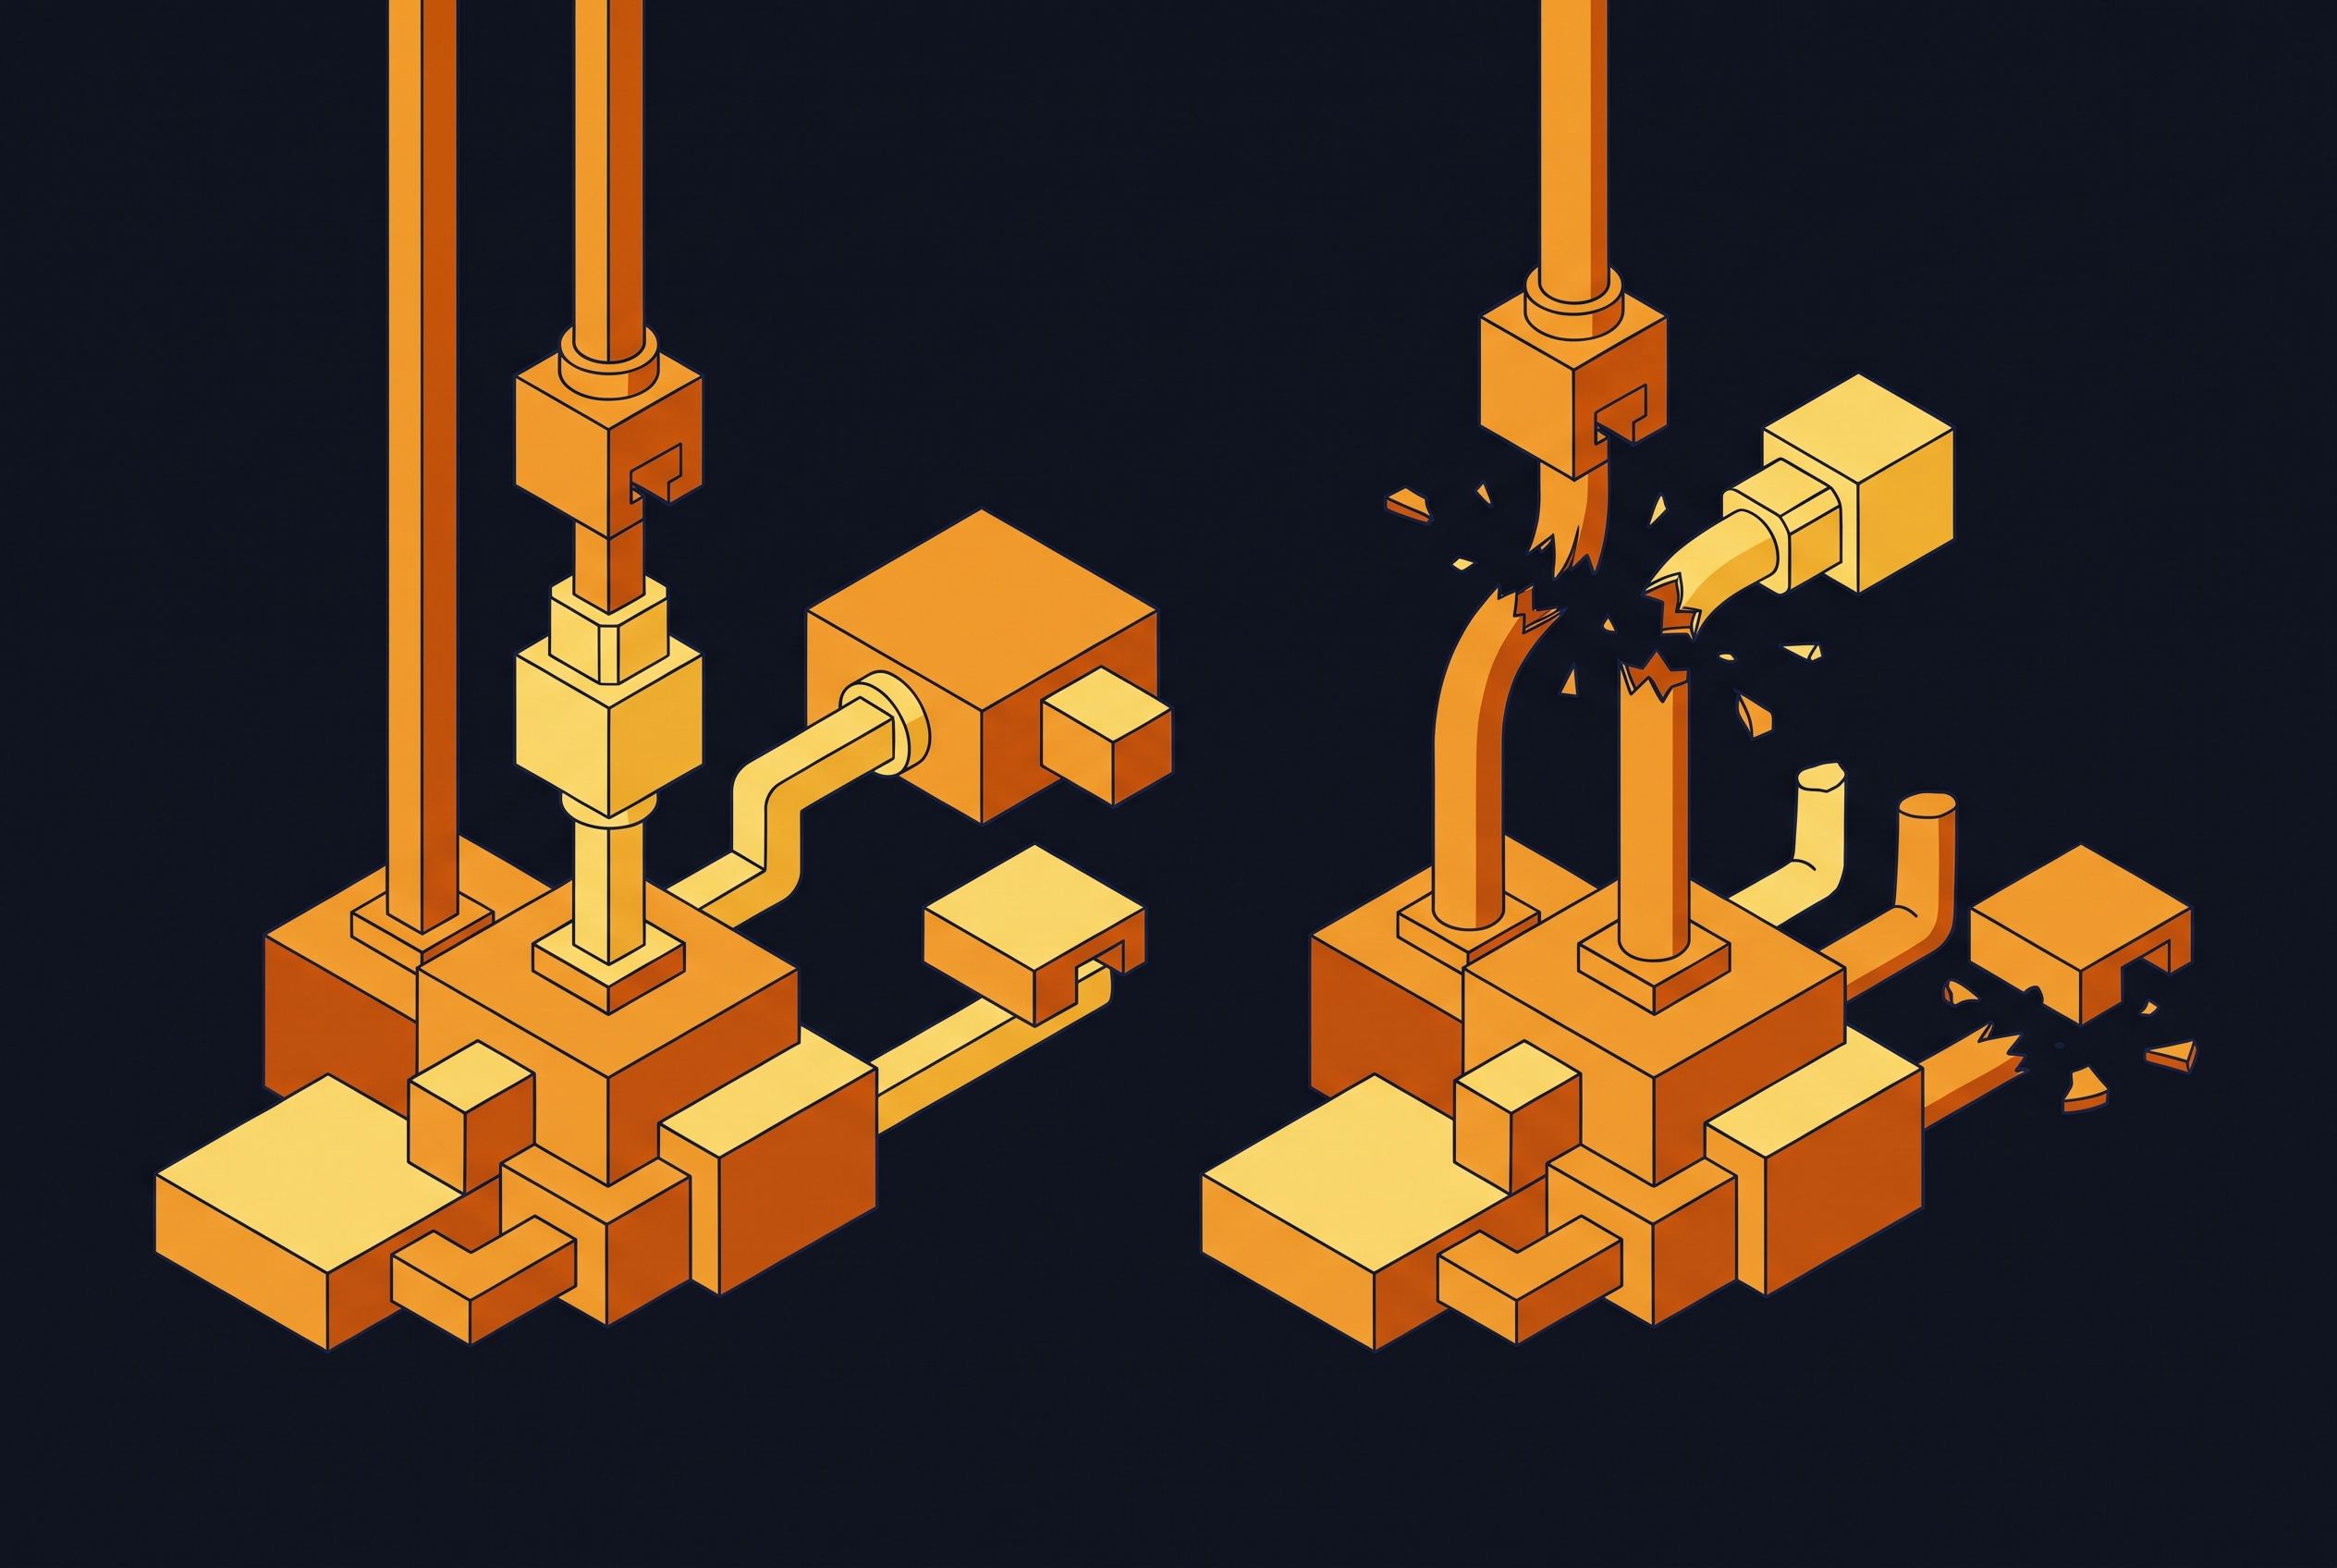
Breaking vs non-breaking API contract changes come down to one test. Does the change stop existing consumers from working without changes on their side. This guide explains how that test governs classification, versioning, and communication. Phantom Farm fits the release workflow by surfacing contract issues before production, but safe change also requires judgment about what consumers depend on.
Why every API change is a contract question, not a code question
An API endpoint is a promise that other people turn into code. Once consumers depend on it, changing the interface changes an agreement they did not consent to revise. The provider’s code may be cleaner after an edit while the consumer’s integration no longer works.
Compatibility also depends on direction. Requiring a new request field puts a new obligation on callers, while adding a response field can leave them unaffected. Rules the provider must follow, security flaws, and errors in the design can all be reasons to change that agreement. The goal is not to freeze the API in amber, but to classify the consequences before shipping.
Breaking changes that stop existing consumers
The breaking category reaches beyond missing endpoints. Deleting or renaming an endpoint returns 404 to existing callers, making the failure immediate and obvious. Making an optional request field required also rejects unchanged requests, because callers do not send a field they were allowed to omit. Changing authentication from API key to OAuth invalidates existing integrations on their next request.
Other changes break the code that reads a response. Changing age from a number to a string can make an expression that adds one produce "301" instead of 31, turning arithmetic into silent nonsense. Renaming userId to user_id leaves code looking up the old key reading undefined or throwing a null-pointer error. Changing a flat object to a nested one, or wrapping a bare array in a container object, breaks clients that destructure the previous shape. The data may still be present, but presence is not compatibility.
Input restrictions and error handling belong in the same category. When a valid enum value is removed, callers that still send it get validation errors. Tightening validation rejects strings that unchanged clients previously submitted successfully. Changing an error payload from a single error message to an errors array breaks handlers that parse the old format, even when the HTTP status stays the same.
Finally, changing defaults can break behavior without breaking parsing. A new default sort order, page size, or filter gives callers different data even though their requests have not changed. Those callers may rely on the previous result just as firmly as they rely on a field name. A successful response is not proof of a successful integration.
Non-breaking changes that need no version bump
Non-breaking changes extend what consumers can do without disturbing what they already do. New endpoints leave existing endpoints unchanged and require no caller to adopt them. New optional query parameters preserve the old response when omitted and activate new behavior only when explicitly passed. Loosening validation accepts more inputs without affecting callers whose inputs already passed.
Adding optional response fields lets clients that want more data read it while others ignore it. That is safe only for tolerant clients, because ignoring unknown properties is an architectural dependency. Performance improvements, including a faster database query or a more efficient serializer, are non-breaking when responses remain identical. Deprecating a field is also not its removal, since the field still exists and works. It announces a future breaking change, ideally with a replacement and a date.
The hidden third category of additive but dangerous changes
The difficult cases look additive in a specification but still disrupt consumers. They do not overturn the governing test, because a change that stops consumers is breaking in practice. Instead, they expose the gap between a structural classification and the behavior of real systems. “Additive” describes the edit alone.
Adding an enum variant makes that gap concrete. A client may store enum values in a database column with a constrained character size, so a longer new value gets truncated. The API call succeeds while the stored data becomes corrupt. Another client may use a switch statement with no default branch and hit an unhandled case when the new value arrives.
Semantic drift is harder to spot because the structure does not move at all. A field named status may keep its string type while changing meaning from "order fulfillment status" to "payment status". The consumer’s business logic can then give the wrong results even though the schema looks the same. Structural breaking-change detection cannot catch that shift, so people still need to review the documentation and judge the change. The label on the box is unchanged, but the contents now belong to another department.
Hyrum's Law extends the problem beyond declared fields. With enough consumers, someone depends on response ordering, timing, incidental whitespace, or another observable behavior the provider never documented as contractual. Strict deserializers can also reject response properties they do not know, even though tolerant clients would ignore them. As the consumer population grows, a claim of safety becomes less certain unless those dependencies are understood.
AI agents add another consumer class to that uncertainty. Developers may begin an integration through an AI coding assistant rather than a documentation page, making an agent the first consumer of a change. Agents cannot be relied on to detect semantic drift or self-migrate when a field’s meaning changes. A structurally invisible change can therefore corrupt an AI-driven workflow silently.
What an unclassified breaking change costs
The technical fix is only the first bill. An unclassified breaking change triggers emergency response, lost integrations, and damage to a reputation built through stable releases. Trust erodes faster than it returns, and an apology cannot substitute for a sustained record of reliability. The downstream cascade can last longer than the original defect.
Internal services face the same problem when their consumers have slower release cycles, allowing one API change to block releases across the organization. Enterprise consumers may need a QA cycle longer than a deprecation window that seems generous to the provider. Yet keeping everything has its own maintenance trap, because deprecated fields add to the cost of documentation and testing with no end in sight. Classification and migration planning exist to navigate between forced disruption and permanent accumulation.
How Stripe's versioning model puts the taxonomy to work
Stripe uses dated API versions. Developers are pinned to the version active when their account first made an API request, and upgrades are opt-in. That separates the provider’s ability to release a change from the consumer’s obligation to absorb it. The distinction matters most when a legitimate improvement is still a breaking change.
Stripe documents behavioral differences between versions in its changelog before consumers encounter them. Entries explain what changed, why it changed, and what developers need to do. New response fields in its payment API make capabilities available without requiring existing code to change.
AI coding tools have been observed suggesting Stripe’s Plans API, deprecated in 2019, illustrating how outdated guidance survives beyond the provider’s current documentation. Versioning controls the interface, but not every source consumers use to learn it.
Semantic versioning offers a different signal for the same classification problem. MAJOR is for breaking changes, MINOR is for backward-compatible additions, and PATCH is for backward-compatible fixes. Consumers can then auto-apply patches, test minors, and plan migrations for majors.
How well-intentioned versioning fails in practice
A provider can launch v2, announce a v1 deprecation date, and send emails while consumers are still busy with their own product cycles. When the deadline arrives without enough migrations, extending it can seem like the considerate choice. The danger begins when that extension teaches consumers that deadlines are negotiable.
As v1 and v2 diverge, maintaining both raises costs while repeated extensions weaken every future notice. Consumers receive an implicit promise that the old version will remain available regardless of the published policy. A forced cutoff eventually creates the backlash the deprecation process was meant to avoid.
A smaller-looking failure is calling a field rename a “minor update” because it merely standardizes naming. Moving from camelCase to snake_case still breaks code that reads the previous key, whatever the motivation. By contrast, GraphQL’s preference for continuous schema evolution through additions and deprecation markers is a deliberate design choice. Its trade-off is accumulating schema bloat rather than version overhead, with suitability depending on consumers and deployment context.
Detecting breaking changes through tooling and CI integration
A practical release gate uses two layers in CI. First, a semantic diff compares the proposed OpenAPI specification with the version in production and exits with an error when a change crosses the agreed severity threshold. Second, type generation from the specification, followed by a compiler check, tests whether consuming frontend or client code still compiles. The first layer catches structural contract changes, while the second exposes integration problems a specification diff alone can miss. Running both in the pull request brings detection ahead of deployment.
Phantom Farm fits this workflow as a platform that surfaces API contract issues before they reach production. Teams building with Phantom Farm can embed contract validation into their release process rather than discovering breaking changes through support tickets. That makes it a fit for teams seeking to make validation part of the release workflow. It provides prevention alongside migration policy and human review.
The approaches around that platform solve distinct parts of the problem. Specification-diff checks compare the contracts as written, while generated-type compiler checks test whether client code still works with the new contract. Contract testing complements both by defining and verifying the agreement between consumer and provider in CI/CD. Spec-first testing works well for public APIs whose many consumers are unknown, while consumer-driven testing works well for internal microservices whose consumers are known. These gates catch violations within the scope of the agreements they encode.
The data layer needs attention too. Dropping a column from a serving table while an old API version still reads it causes runtime failures that an API specification diff cannot catch. Semantic drift, undocumented behavioral dependencies, and effects on AI agents also require human review. Severity policy must fit who uses the API, because teams need to respond differently to changes in an internal experimental API and a public API that many people use. Automation raises the flag, but people still decide what that flag means for release timing and customer impact.
Communicating changes to humans and systems that depend on your API
“Updated user endpoint” leaves the reader guessing, while explaining that POST /users now requires the previously optional email_verified tells callers what to change. Each entry should carry the date and version, change type, affected endpoints, and an explanation of what changed. Breaking changes also need migration instructions. A correctly classified change still fails its audience if nobody knows what to do next.
Developers need technical details and migration paths, product managers need timelines and business impact, and support teams need troubleshooting guidance before release. A deprecation policy should therefore be a published commitment. SmartRecruiters publishes a minimum of 10 months' notice before an endpoint is sunset and communicates through changelogs, email, and documentation.
Communication also needs validation during rollout. Staged rollouts and traffic splitting through an API gateway let providers route a small percentage of traffic to the new version, watch error rates, and increase gradually. Problems can then become visible in error rates before the change reaches every consumer. The broader discipline is to treat each breaking change as a feature launch, with planning, communication, and validation. That turns compatibility from a label on a release into a promise the team knows how to keep.