API Key Lifecycle Management in Production Systems
Leaked API keys compromise infrastructure faster than teams can track or revoke them.
In 2024, attackers broke into the US Treasury Department without cracking a single encryption algorithm. They used a leaked API key for BeyondTrust's Remote Support SaaS platform, and that one credential walked straight past every other security investment the department had made. That is the lifecycle problem in a single incident: the key worked exactly as designed, for exactly the wrong person, for far longer than anyone intended.
API keys are static, long-lived bearer credentials. Whoever holds the key gets access. The key authenticates itself, not the person or service presenting it. That single design fact explains almost everything that goes wrong with them later.
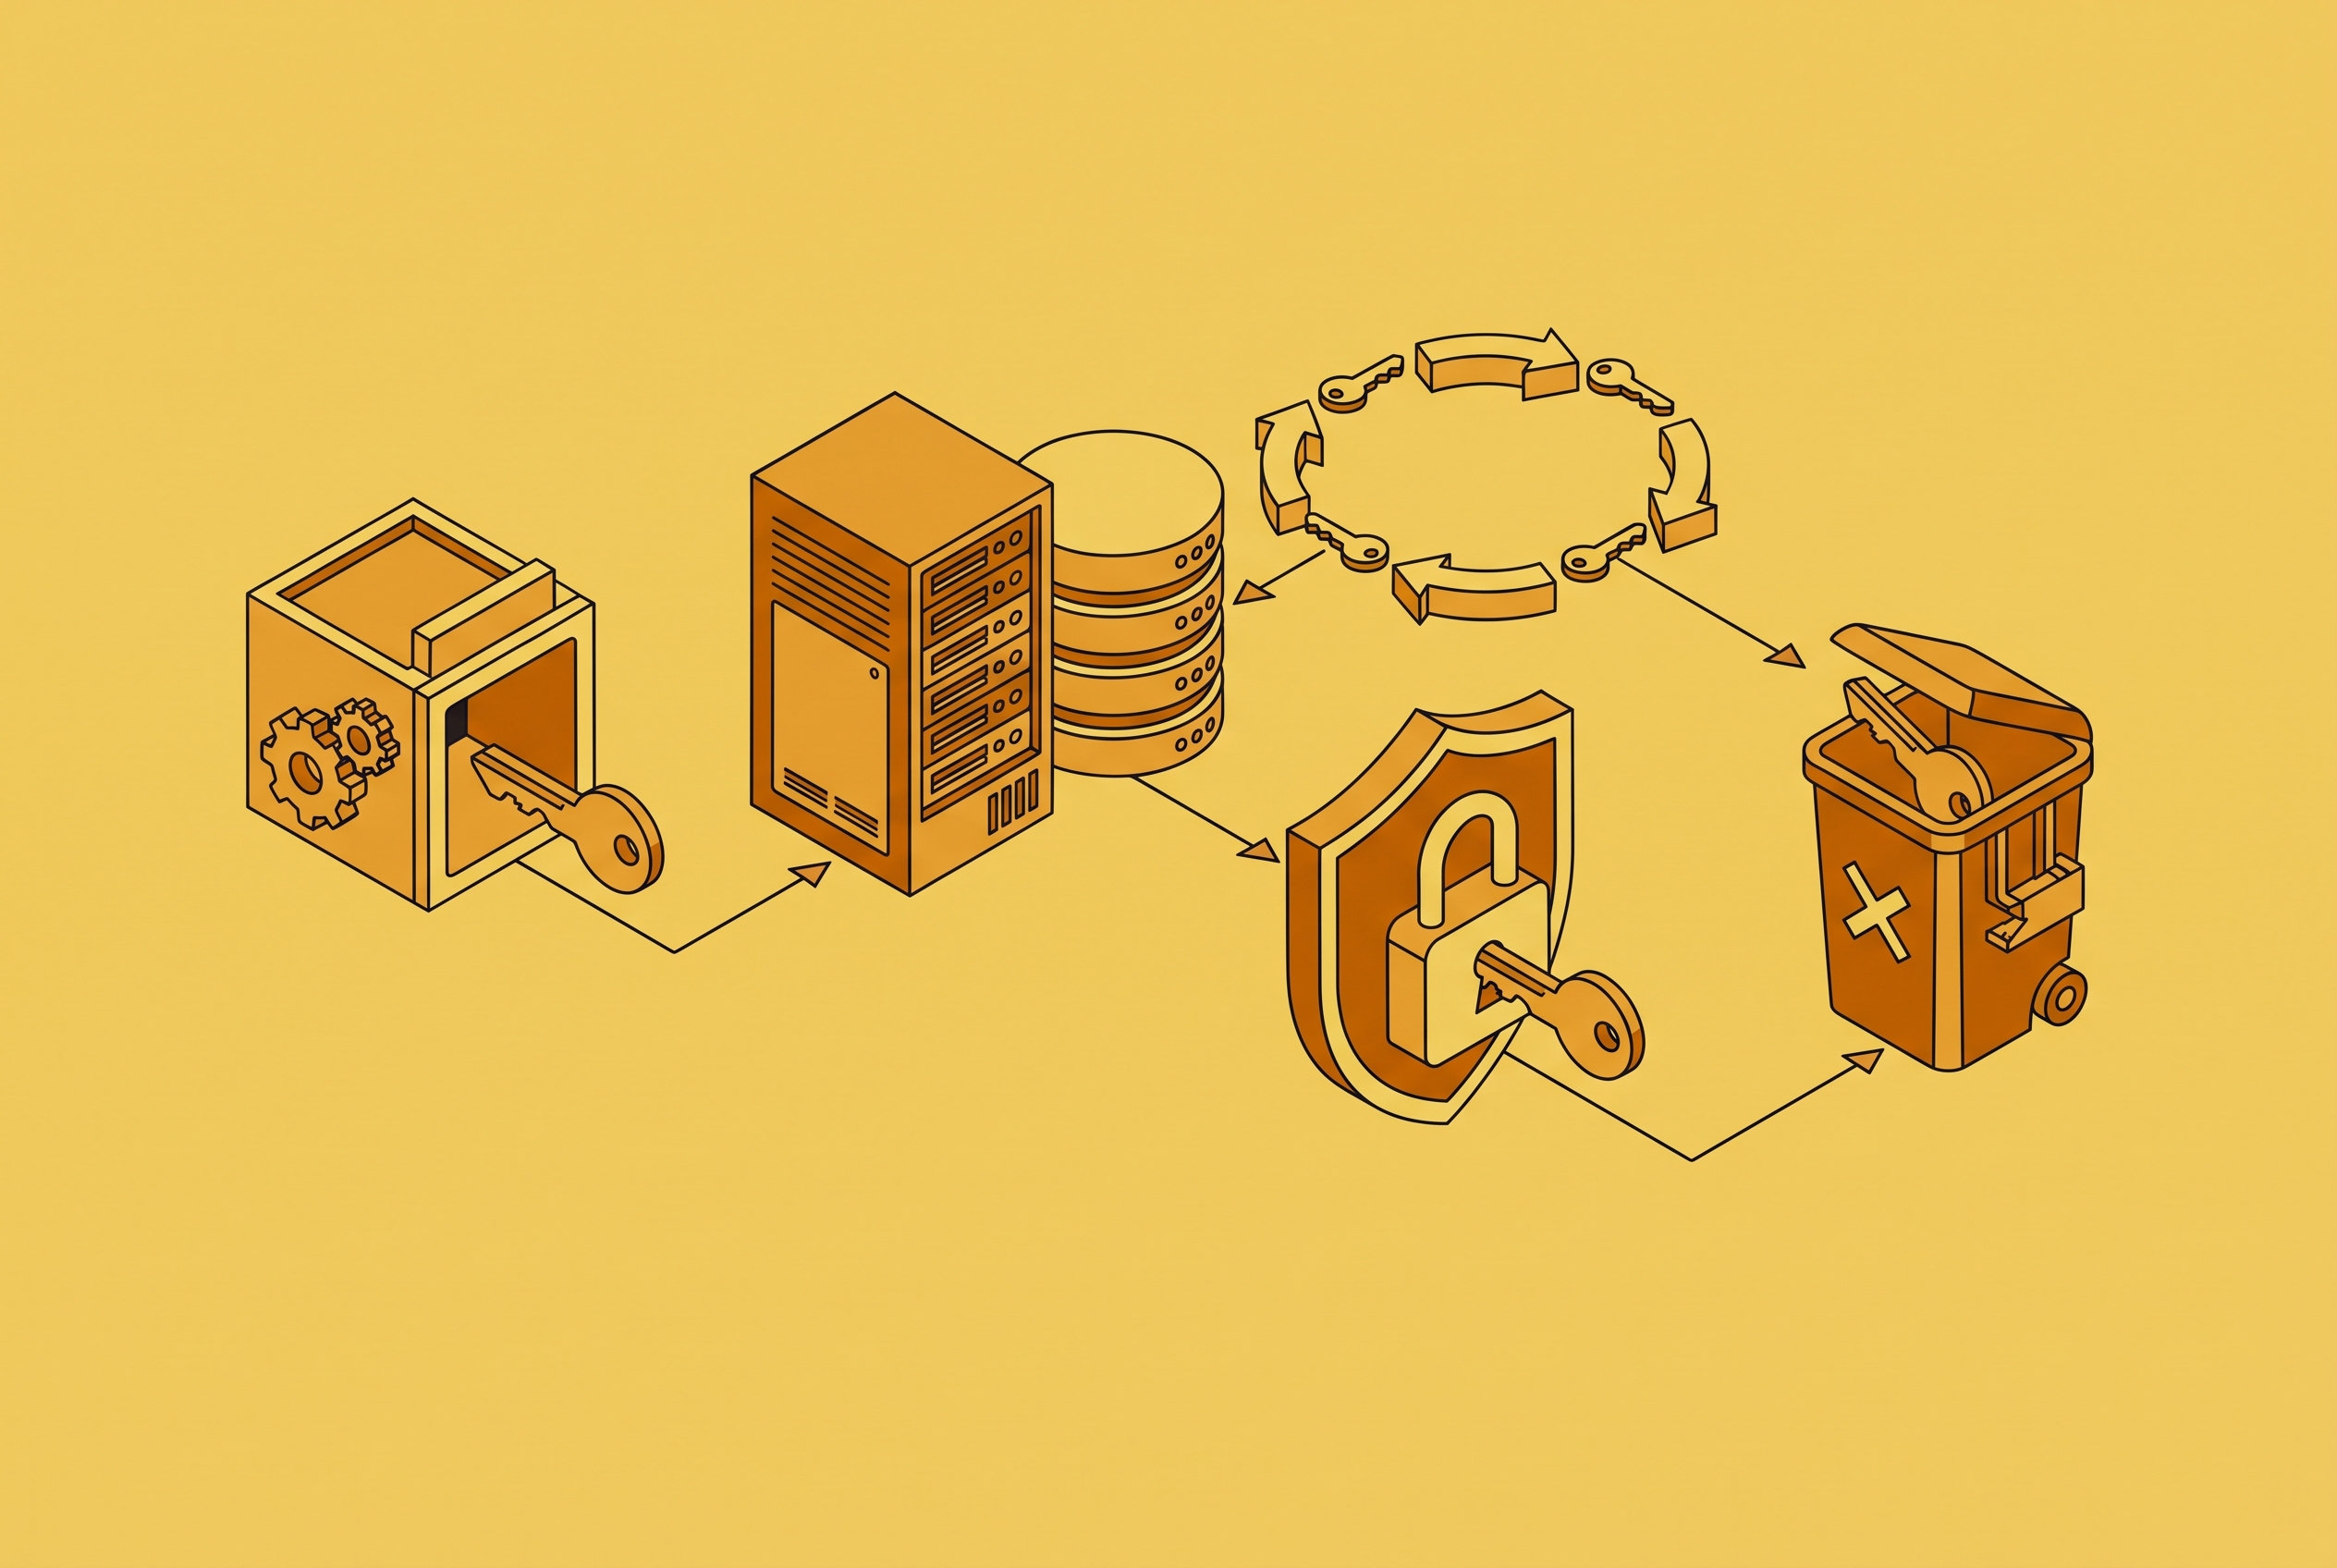
Storage advice (don't hardcode it, keep it out of source control, put it in a vault) is good advice, and teams should follow it. But a key can be stored with perfect hygiene and still turn into a liability, because storage only covers one moment in a much longer life. The scope was never defined. The owner left the company eighteen months ago. Nobody has rotated it since the day it was created. None of that is a storage failure. It's an ownership failure stretched across time, and that stretch is what this piece calls the lifecycle: issuance, storage, rotation, monitoring, revocation, each one a separate control, each one capable of failing on its own.
The Klue breach in mid-2026 makes the same point from a different angle. A GitHub personal access token issued back in 2022 for a limited pilot program and never decommissioned was the entry point. In September 2026, Veradigm suffered a breach where credentials lifted from a vendor's environment were used against a Veradigm API, returning patient data that included Social Security numbers. Three breaches, three industries, one shared root cause: nobody owned the full arc of the key's life.
The scale at which unmanaged keys accumulate in real production environments
Machine identities now outnumber human users in most organizations by a wide margin, and the tools built to govern those identities have not caught up. API keys, service accounts, and machine tokens multiply quietly in the background while security teams are busy managing the humans who are easier to see.
This isn't a story about careless engineers leaving keys lying around. Every new microservice integration creates a credential, and every third-party API onboarding creates another. Every CI/CD pipeline generates its own set, often automatically, often without anyone writing the key down anywhere a security team would think to look. Sprawl is a structural byproduct of how modern systems get built, and most teams simply have no centralized register tracking what exists, who owns it, or whether it's still needed.
AI agents are pouring fuel on that fire. Agents make far more API calls than a typical application does, and they pass keys through more places along the way: logs, prompts, MCP configuration files, intermediate steps that a human developer would never have generated. Agents also tend to create credentials in environments with far less visibility than a traditional deployment pipeline. That compounds the sprawl problem faster than teams can track it.
The attack surface this creates is not hypothetical. Researchers found 19 npm packages built specifically to install rogue MCP servers inside popular AI coding environments, including Claude Code, Claude Desktop, Cursor, VS Code Continue, and Windsurf. The target was API keys belonging to multiple LLM providers, pulled straight out of coding tools developers trust by default. Nothing in the prior decade of credential management frameworks anticipated an attack class built specifically around the AI development workflow. The old playbook assumed keys lived in config files and environment variables. It did not assume keys would be sitting inside a coding assistant's memory, waiting for a malicious package to come looking.
What a complete key inventory must capture
Rotation, monitoring, and revocation all depend on one prerequisite: knowing the key exists in the first place. A team cannot rotate a credential it has forgotten about, and it cannot revoke access it never recorded granting. The inventory is the foundation everything else in the lifecycle sits on, and most organizations skip it.
A useful inventory records, for every key: the owner, the application it belongs to, the environment it runs in, its scope, its creation date, the date it was last used, its rotation date, and the routes it's approved to call. That's eight fields, and skipping any one of them turns the inventory from an operational tool into a list that looks complete but isn't. Six months later, two services depend on a credential nobody remembers issuing.
A working inventory changes what happens during an incident. Without the inventory, that lookup becomes an investigation, and investigations take hours or days, time an active breach does not wait around for.
Keys leak most often in places security teams aren't watching. The Stripe legacy API incident in 2025 shows the other blind spot: attackers didn't touch Stripe's core infrastructure. They went after a deprecated endpoint that nobody was watching closely anymore, which proves a simple point: a key on an abandoned endpoint is exactly as dangerous as a key on one still in active use, maybe more so, because nobody's looking at it.
An inventory built once and never touched again is already going stale by the time it's finished. Every new key creation should update the register automatically. Organizations that report they don't track the creation of new AI-related identities at all have the widest inventory gap on record right now, and that gap is also where the attack surface is most exposed.
Scoped issuance: giving each key the minimum access it needs
The permissions a key is handed at birth set the ceiling on how much damage it can do if it's ever stolen. That makes scope a decision made at issuance, not a patch applied after something goes wrong. Over-permissioning a key up front is a risk baked into the system before the key has made a single call.
Plenty of API keys get issued with far more access than the requesting service will ever use. Least privilege, done right, means separate keys for separate contexts: one for development, one for staging, one for production, separate ones again for internal services, partners, and anything considered high-risk.
Reusing the same key across production and staging is an anti-pattern plenty of teams are repeating right now without thinking twice, and it feels efficient. It's actually a decision to erase the wall between two environments that should never touch. If the staging key leaks (and staging environments tend to have looser security than production, almost by definition) the production environment is compromised the moment that leak happens, because it was never actually a separate environment from a credentials standpoint.
Smaller scopes pay off twice. A partner key calling a private administrative route should trip an alarm, not slide through unnoticed.
Where the key travels matters as much as what it can do. Query parameters put keys in server logs, browser history, and referrer strings, which is a bit like writing a password on a sticky note and leaving it taped to the monitor; it's visible to far more systems than anyone intended. Passing the key through a header instead keeps it out of those exposed channels. Keys should never appear as query parameters in a production system.
AI agents complicate scope further, because an agent doesn't behave like a traditional application calling a fixed set of endpoints. Agents make runtime decisions about which API to call next, so scope has to be defined per-agent and per-task. That's a bigger shift than it sounds, and the monitoring section ahead picks it back up.
None of this works if it lives only in someone's memory. Issuance decisions belong in the inventory the moment the key is created: scope that isn't recorded anywhere isn't enforceable, a rule nobody can check.
Secure storage: where keys must and must not live in a production system
Storage hygiene is necessary, and on its own it is not enough. A key kept out of the wrong places still needs to live inside a system that gives the team access control, audit logs, and a way to rotate the key without anyone touching application code.
The basics are familiar enough that most practitioners could recite them: no hardcoding keys into source code, no checking them into source control, no pasting them into support tickets, no stashing them in plain-text configuration files. Keys belong on the server side or inside a secure vault, full stop.
A secrets manager earns its keep by providing three things at once: access control over who can retrieve a key, audit logs of every time it's touched, and encryption at rest.
HashiCorp Vault's dynamic secrets feature shows what the strongest version of this control looks like in practice: a credential gets generated on request, carries a time-to-live, and revokes itself automatically when that window closes. The key never sits anywhere in plaintext, waiting to be found. Transmission hygiene rounds this out. Calls should run over TLS, systems that receive keys should avoid logging the full value, and wherever it's practical, teams should store only a hash or an identifier for lookup purposes, keeping the actual secret out of routine logs. Google's own documentation recommends moving away from API keys altogether in favor of IAM policies and short-lived service account credentials, and storage risk sits at the center of that recommendation.
The real payoff of good storage shows up at the next stage of the lifecycle. A key sitting in a vault can be rotated programmatically, with no code deploy and no engineer manually swapping a value at 11 p.m. Storage done right makes rotation possible without anyone having to hold their breath.
Rotation on schedule and on event: designing it so it happens
Most organizations will say rotation matters. Few actually do it on any reliable cadence, and the reason isn't disagreement about its value: rotation, as most teams have built it, is a risky manual operation that something always seems to go wrong with, and nobody wants to be the one who breaks production on a Tuesday afternoon. Manual rotation fails because the fear of an outage creates constant pressure to put it off, and every postponement extends exactly the exposure rotation was supposed to close.
Fixing that means designing rotation differently. The overlap pattern is the single most useful idea here, and it deserves more attention than any calendar reminder ever will. Instead of swapping an old key for a new one in one risky instant, the system lets both keys stay valid at the same time for a short transition window. Traffic moves over to the new key gradually, under observation, and only once the team can see that nothing is still using the old one does that old key get revoked. The "big bang" cutover disappears entirely, and with it goes most of the hesitation that keeps rotation from happening on schedule.
Cadence should track risk. A key sitting behind a production payment system or an identity provider warrants a tighter rotation window than a low-privilege, read-only reporting key that barely touches anything sensitive. A production window in the range of 30 to 90 days is a reasonable baseline to build from, adjusted up or down based on what the key can actually reach.
Rotation shouldn't wait for the calendar either. Any one of those should be enough to force a rotation on the spot, without waiting for the next scheduled window to roll around.
None of this holds up if the rotation runbook has never actually been run. A procedure that only exists on paper is a procedure the team is testing for the first time in the middle of an incident, which is the worst possible moment to discover that step four doesn't work the way the documentation says it does. Automating rotation through the secrets manager closes the loop completely: the vault generates the new key, pushes it out to every dependent service, and retires the old one, with no human standing in the critical path where a mistake could cost an afternoon.
Monitoring key behavior, not just key validity
A valid key and a legitimate request are two different things, and most monitoring setups only check for the first one. Authentication success confirms the key works. It says nothing about whether the thing the key is being used for right now is something it should be doing.
Closing that gap means watching behavior, not just checking a box at the door. Useful signals include the route being called, the method, the status code coming back, the source network and ASN, the country the request originated from, the user agent, the request rate, the error rate, the response size, and the time of day the call came in. None of those signals on its own proves anything. Together, they build a picture of what normal looks like for a given key, which makes it possible to notice the moment something stops looking normal.
Monitoring catches what inventory, scoping, storage, and rotation all miss between them. A key can be issued with the right scope, stored in a proper vault, and rotated right on schedule, and still get used by someone who stole it the day before the next rotation was due. Monitoring is the one control built to catch exactly that gap, watching the key's behavior in real time rather than trusting that everything upstream in the lifecycle went the way it was supposed to.
Sources
- Best Practices for API Key Management and Rotation
Informed the transmission hygiene guidance on avoiding logging full key values and the behavioral monitoring signals section.
- API Key Rotation: Zero-Downtime Lifecycle Guide - Zuplo
Informed the rotation section, particularly the overlap pattern for zero-downtime key transitions and cadence recommendations.
- Best Practices: API key management - Endor Labs Documentation
Informed the inventory requirements section and the principle of separate keys for separate contexts and environments.
- API Sprawl Leads to API Chaos: Regain Control of Your Enterprise - digitalML
Informed the section on how API sprawl accumulates structurally through microservice integrations and CI/CD pipelines.
- 10 API Key Management Best Practices
Informed the secure storage section covering secrets managers, audit logs, encryption at rest, and TLS transmission requirements.
- API Key Management
Informed the explanation of API keys as static bearer credentials and the core lifecycle stages of issuance, rotation, and revocation.
- How to Become Great at API Key Rotation: Best Practices and Tips
Informed the rotation cadence guidance and the recommendation to trigger immediate rotation on specific events rather than waiting for scheduled windows.